Customer support triage
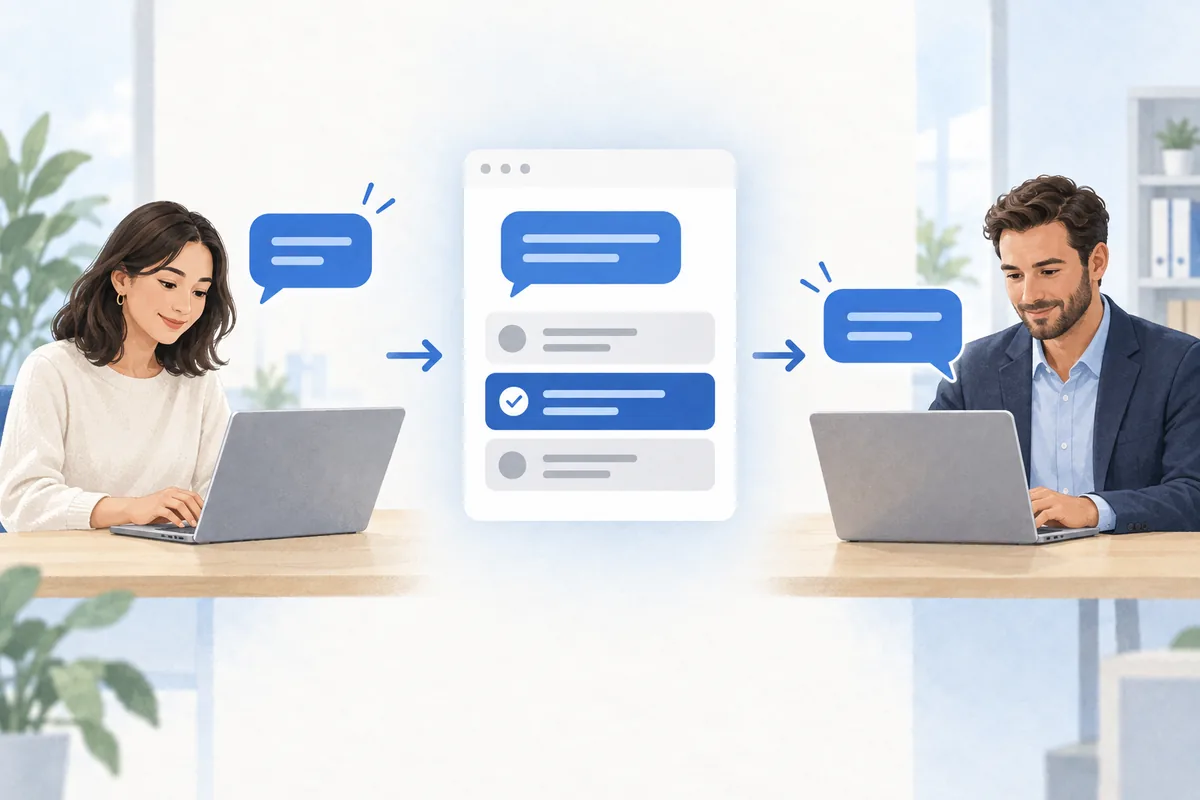
Identify the intent and topic of incoming messages. Give your help desk the signals it needs to route clear cases and review uncertain ones.
JEV API
Detect customer intent, route requests, and score content relevance. Turn text into classifications, probabilities, and scores with JEV, TypeSafe's System One model, so your app or agent can decide what happens next.
We plan to integrate your API next month, with around 100,000 requests per month. Which plan would fit our team?
MEET JEV
Customer messages, product descriptions, and document passages contain information your software needs to interpret. JEV is TypeSafe's System One model for these judgments. It evaluates the context you provide against your criteria and returns categories, truth probabilities, or scores.
Use it at the point where a workflow needs to understand content and choose what happens next. A language model can draft a reply or summarize a document; JEV can help select a route, choose relevant material, or check whether a reply meets your requirements. Your application puts the decisions into action.
USE CASES
Use JEV where your workflow repeatedly reads content, evaluates it against criteria, and decides how to handle it.
Identify the intent and topic of incoming messages. Give your help desk the signals it needs to route clear cases and review uncertain ones.
Score retrieved passages against a user's question. Use the scores to rank candidates and select useful context for an answer.
Assess a request's domain and complexity. Let your application choose a specialist agent, a language model, a simple rule, or human help.
Check whether an answer addresses the question, follows your policies, and is supported by the provided context. Flag questionable results for review.
Evaluate company fit and purchase intent against your criteria. Prioritize inbound leads and surface the conversations worth following up.
Organize reviews, survey responses, and support conversations by topic and sentiment. Turn open-ended feedback into categories your team can track.
PUTTING DECISIONS TO WORK
Use noul for a yes/no question such as whether a customer is asking about pricing; it returns the probability that the condition is true. Use choice when the next step depends on a category, such as sending an inquiry to sales, support, or account management.
Use score when the distinction is ordered: for example, whether a passage only mentions a topic, partly answers a question, or answers it directly. The result can fall between levels, reflecting the distribution across your criteria. These three question types let you ask for the judgment your workflow needs instead of parsing it from a written reply.
See a customer inquiry triage exampleStart with the action a classification should lead to. For customer inquiries, your categories might be plan selection, integration guidance, and account management. Describe what belongs in each category, and provide the message along with any product context needed to tell them apart.
One message can contain more than one useful signal. Evaluate its topic, purchase intent, and timing as separate questions over the same context. Your application can then choose a team and a follow-up priority without forcing every detail into one category.
A useful scoring scale describes observable differences. For search relevance, a passage might merely mention the topic, answer part of the question, or directly answer it. Those descriptions make the score more useful than labels such as low, medium, and high alone.
Keep different goals separate. A passage may be relevant but incomplete; a sales lead may fit your target market but have no clear purchase timeline. Evaluate each dimension separately, then rank or filter results using the priorities that matter to your business.
Some messages fit two categories, and some records lack the facts needed for a decision. Use the answer distribution to spot ambiguity. Your workflow can request more information, use another check, or route the case to someone who can review it.
Before enabling automatic actions, test representative examples from your own work, including edge cases. Compare the decisions with your team's judgments and adjust the criteria and thresholds. Confidence helps you choose a handling policy; it does not guarantee that an answer is correct.
TRY IT, THEN INTEGRATE
Test the decisions first, then bring them into your application or agent.
Try real examples, define categories or scoring criteria, and inspect both clear and ambiguous cases. Export your request when ready.
Add classification and scoring to support, search, or business workflows. Your application decides when to act, review, or take another step.
Let MCP-compatible agents evaluate candidates, choose a route, or check an answer before taking action.
USAGE-BASED PRICING
Pay for input usage; output is free. Start with a small evaluation and expand to everyday classification, filtering, and scoring.
JEV is TypeSafe's System One model for AI decisions. It evaluates text or structured context and returns classifications, probabilities, and scores that software can use for routing, filtering, and prioritization. Sukidata provides access through its API, Playground, and MCP.
Use JEV when the next step is a decision: choosing a team, scoring relevance, or checking a condition. A language model can handle open-ended writing or conversation. For example, JEV can route a support request before a language model drafts a reply.
Yes. Define the conditions, categories, and ordered scoring levels that match your workflow. You can evaluate several questions against the same context in one request, such as a message's topic, purchase intent, and urgency.
Test JEV against representative examples from your business and choose thresholds for automatic handling or review. Probabilities and confidence help distinguish uncertain results, but they do not guarantee correctness. Keep human review for consequential decisions.
Start in the JEV Playground with a real message, document excerpt, or structured record. Define what you want to evaluate, inspect the answers, and export the request when you are ready to connect your application. Agents can also use JEV through MCP.